Questions understood
The model chose the intended query.
WORKSHOP / TEST REPORT
Local models on a MacBook with 48 GB RAM. We test how well they handle everyday tasks using fictional examples.
New on 7 October 2026: Kolibri, Kev and Gemma in a larger local Folio test →
24.09.2026 · 14 FICTIONAL EXAMPLES
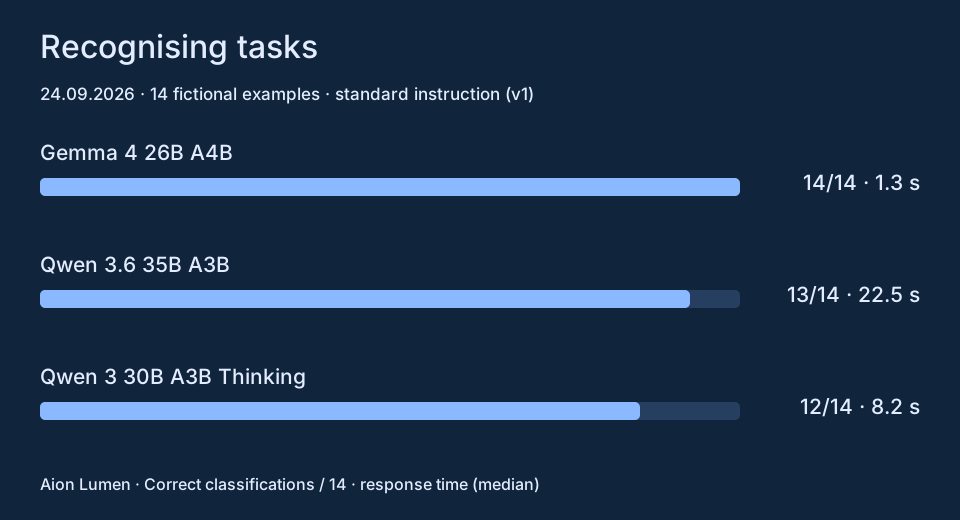
Three models classify the same messages: task, unclear or no task. Standard instruction (v1).
We also tried a more specific instruction on the same fourteen messages. Gemma stayed ahead in both versions.
| Model | Instruction | Correct | Time · median |
|---|---|---|---|
| Gemma 4 26B A4B | Standard (v1) | 14/14 | 1.3 s |
| Gemma 4 26B A4B | More specific (v1-strict) | 14/14 | 1.3 s |
| Qwen 3.6 35B A3B | Standard (v1) | 13/14 | 22.5 s |
| Qwen 3.6 35B A3B | More specific (v1-strict) | 12/14 | 23.2 s |
| Qwen 3 30B A3B Thinking | Standard (v1) | 12/14 | 8.2 s |
| Qwen 3 30B A3B Thinking | More specific (v1-strict) | 13/14 | 9.2 s |
In Ledger, Qwen 3.8 interprets the question. Code retrieves transactions and calculates the answer.
The model chose the intended query.
The path from question to answer; nine cases used the model.
Queries and totals checked directly in code.
DEVELOPMENT
August–September 2026
We first compared local models on email. Some returned empty or unreadable answers. Response quality, speed and manual checks guided the selection.
22 September
Ledger taught us to test question understanding and calculations separately. After improvements, the workflow reached the results shown above.
24 September
Three models tried two instructions. We discovered that our expected answer for a meeting note was wrong and rescored the saved responses; the charts now show those results.
Today
Response quality, speed and manual checks guide the choice of mail models. The catalogue brings together twelve candidates from separate experiments; the two Qwen versions belong to the same family.
A useful next step: try Gemma 4 26B on more mail edge cases and tool calls.
← Back to the lab